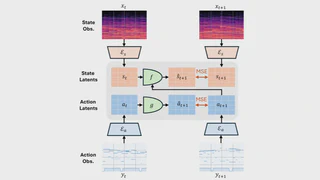
Music-JEPA: Learning a World Model of Sound from Action2026-07·Ziyu WangKun Fang,Yann LeCun· 0 min read paperTypePreprintPublicationarXiv preprint arXiv:2607.22000Last updated on 2026-07 AuthorsKun Fang (she/her)PhD Student in Music Technology ← Note-Level Temporal Grounding of Musical Concepts in Large Audio-Language Models 2026-08Revisiting Music Encoding for Music-to-Text Large Language Models: What Is Encoded and What Is "Heard" 2026-06 →
 ,·
0 min read